By now, most people have a pretty good idea of what an AI agent is. The more interesting question is what it takes to move one from a working demo to something that is actually ready for production.
At its core, an AI agent is a software system that uses a language model to interpret a request and decide how to complete it through the tools and systems available to the application. Unlike a standard chatbot, it can do more than generate a response: it can search for information, update records, call APIs, or move through several steps based on what happens during execution.
Building a basic version in a controlled environment is relatively straightforward. Things get more complicated when that agent starts working with real users, different permission levels, external services that can fail, and actions that affect production systems.
At that stage, the main questions are no longer limited to how the model interprets a request or chooses a tool. The application needs to determine what the agent is allowed to do, validate every action before it is executed, preserve enough state to recover from failures, and provide the engineering team with a clear record of what happened during each run.
A successful prototype may show that the model can complete a task under favorable conditions. A production implementation also needs to remain understandable and controlled when the result is incomplete, incorrect, or unexpected. This article focuses on the architecture decisions involved in that transition and explains how to design an AI agent that can operate reliably beyond a controlled demo.
Key Takeaways
- Begin with the smallest architecture that can handle the workflow.
- Keep permissions and business logic in the application rather than relying on model instructions.
- Define how an execution stops, retries, and recovers before exposing the agent to production traffic.
- Treat execution state, long-term memory, conversation context, and retrieval as separate architectural concerns.
- Use model-driven decisions only in the parts of the workflow where flexibility is actually needed.
Start with one agent and a small toolset
One of the first architecture decisions is how much autonomy the system actually needs. Teams sometimes introduce planning, routing, shared memory, and specialized agents before they have confirmed that a single agent cannot handle the workflow. Each additional layer creates another place where state can diverge or an execution can become difficult to trace. For a first production version, start with something smaller:
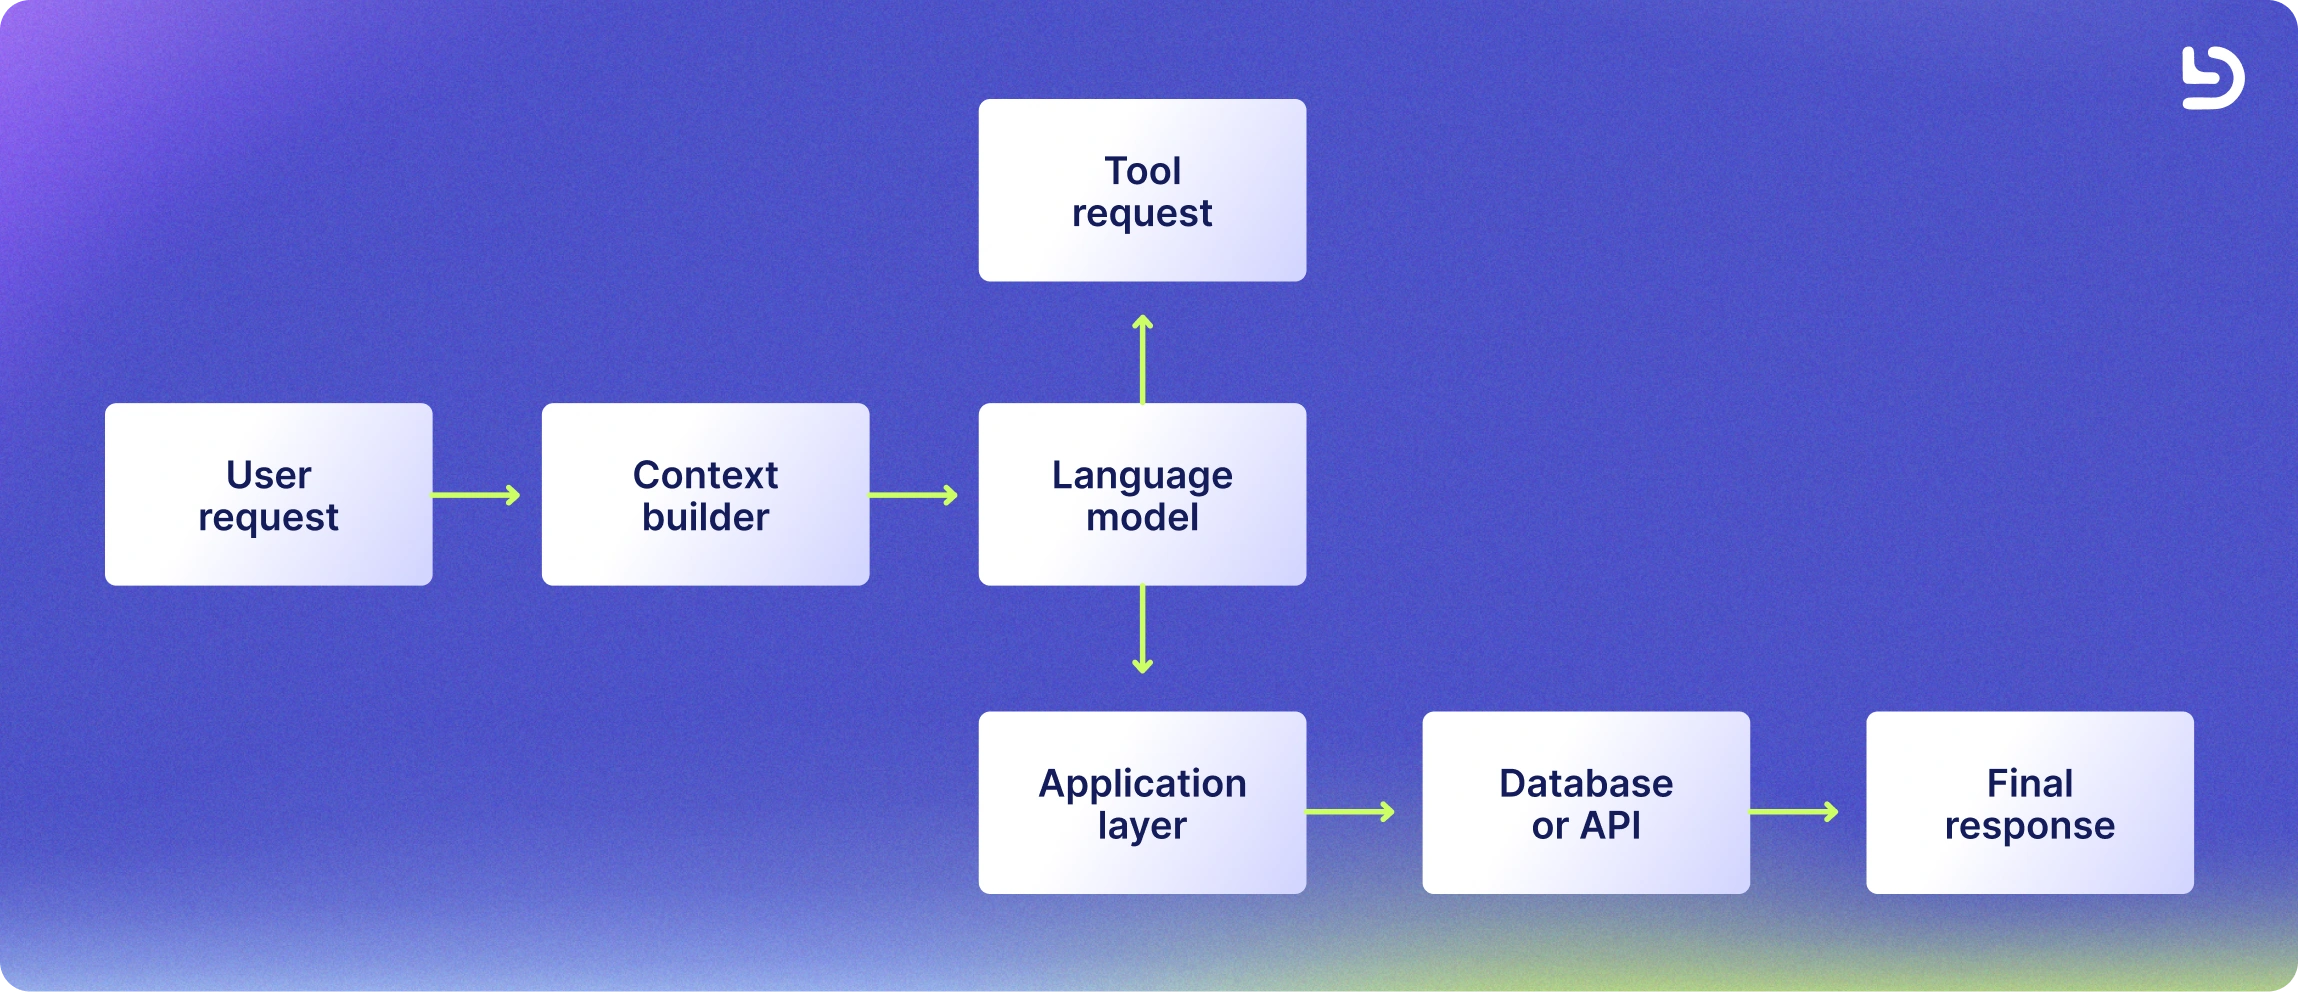
The model interprets the request and selects a tool. The application validates it, executes the operation, and returns a structured result.
In my experience at Devlane, introducing multiple agents too early makes debugging significantly slower because a failure may originate in the routing logic, the transfer of context, or the way state is shared between components. With a single agent, the path from the user request to the tool result is easier to reconstruct.
Multiple agents become useful when the separation reflects a real architectural boundary, whether that boundary comes from permissions, domain ownership, or the amount of context each component needs to manage.
Keep business rules outside the model
The model can propose an action, but the application must decide whether that action is valid and permitted. Authentication, authorization, and business rules should never depend only on the prompt.
Suppose an agent can update a project management system; the model may request an issue assignment, but the application must verify that the user can perform it.
The same applies to validation. If priority has four supported values, validate it with code. A prompt may explain the rules, but it should never be the only enforcement mechanism. Tool design matters here. Early in an implementation, teams often expose every API endpoint as a separate tool:
- create_issue
- update_issue
- assign_user
- change_priority
- add_comment
This creates overlapping choices. Business-oriented tools are usually clearer:
- manage_issue
- search_issues
- get_project_information
Grouping related actions can make the toolset easier for the model to navigate, but only when those actions share similar permission and risk requirements. Sensitive operations, such as deleting an issue or transferring its ownership, should remain separate so they can be validated and authorized independently.
The application translates manage_issue into the correct API calls. A tool that is too broad is difficult to validate, while tools that are too narrow create a confusing registry. In practice, the most useful boundary is usually a recognizable business operation whose inputs, permissions, and possible failures can be defined clearly.
Prompt injection is another reason why control cannot remain inside the model. Documents, websites, and tool responses may contain text that attempts to redirect the agent or influence subsequent actions. The application must treat that content as data, preserve the original permission boundaries, and validate any requested operation independently of the instructions found in retrieved material.
Build a bounded agent loop
Each model decision takes place within an execution loop. The model receives the current state and may return either a final response or a request to use a tool. Once the application has validated and executed that request, the result is added to the state and becomes available to the next model call. This continues until the task is completed or the application decides that the run should stop.
A simplified implementation looks like this:
def run_agent(request, user, max_steps=8):
  state = create_initial_state(request, user)
    for step in range(max_steps):
      decision = model.next_action(state)
        if decision.type == "final_answer":
          return decision.content
            validate_permission(
              user=user,
              tool=decision.tool,
              arguments=decision.arguments,
            )
              if state.is_duplicate(decision):
                return escalate("Repeated tool call")
                  action = state.register_action(
                    tool=decision.tool,
                    arguments=decision.arguments,
                  )
                    result = execute_tool(
                      decision.tool,
                      decision.arguments,
                      timeout_seconds=20,
                      idempotency_key=action.idempotency_key,
                   )
  state.complete_action(action.id, result)
  state.add_observation(result)
  return escalate("Maximum number of steps reached")
The loop needs explicit stopping conditions that the application can enforce independently of the model. A run should not be able to continue indefinitely because the model keeps reformulating the same action or retrying a dependency that will not recover. Those conditions may depend on the number of model calls, elapsed execution time, accumulated cost, or evidence that the state is no longer changing in a meaningful way.
Tool responses should be structured. Instead of returning a paragraph that says an item could not be found, return something like:
{
  "status": "not_found",
    "retryable": false,
    "resource": "customer"
}
This gives the model a clear observation and the application a reliable value to log and test.
Separate state, memory, and retrieval
The word “memory” is used too broadly in agent discussions. It helps to separate it into four concerns:
Putting everything into the prompt makes context grow, increases cost, preserves stale facts, and may expose sensitive information unnecessarily.
In a project developed at Devlane for Fundrise, we built AWS serverless workflows that retrieved Census data, demographic information, Federal Reserve rates, and other market inputs. The workflow stored the progress of each execution separately from the datasets, which remained in their source systems and were retrieved when needed. When a Lambda function or an external API failed, processing could resume from the last completed step instead of restarting the entire workflow.
Agent state should be designed like application state, with a schema, retention policy, and recovery strategy. Durable memory requires extra caution. Store only approved information and retrieve current knowledge from its source rather than keeping a copy indefinitely.
Let the workflow determine the architecture
Most production architectures can be understood as variations of a few recurring patterns:
A reporting process, for example, may always retrieve the same information before validating it and preparing a summary for approval. There is little value in asking a model to rediscover that sequence during every run, so the workflow can remain deterministic while the model handles the parts that require interpretation.
Planning becomes useful when the path depends on information discovered during execution, while routing is more appropriate when different requests belong to clearly separated domains. Evaluation loops are valuable only when the system has a measurable condition for accepting or rejecting the output.
The architecture should follow those requirements. Starting from a framework’s preferred pattern and adapting the workflow around it often introduces model calls and state transitions that the product does not actually need.
Add human approval where it changes risk
Human approval should be reserved for the point at which an agent is about to create a meaningful consequence outside the conversation. When users are asked to confirm routine or harmless tool calls, approval becomes a habit rather than an actual control.
Require approval before actions that are external, difficult to reverse, or high impact:
- Sending an email or publishing content
- Changing customer or financial data
- Running generated SQL against production
- Creating or deleting cloud resources
- Making a purchase or accepting a commitment
Before execution, the user should be able to understand the operation being proposed, the resource it will affect, and whether the outcome can be reversed. Any later change to the target or parameters should invalidate the approval.
Design for failures you can explain
Standard application logs are rarely enough to reconstruct an agent run because the outcome also depends on the model version, the context it received, and the sequence of tool interactions.
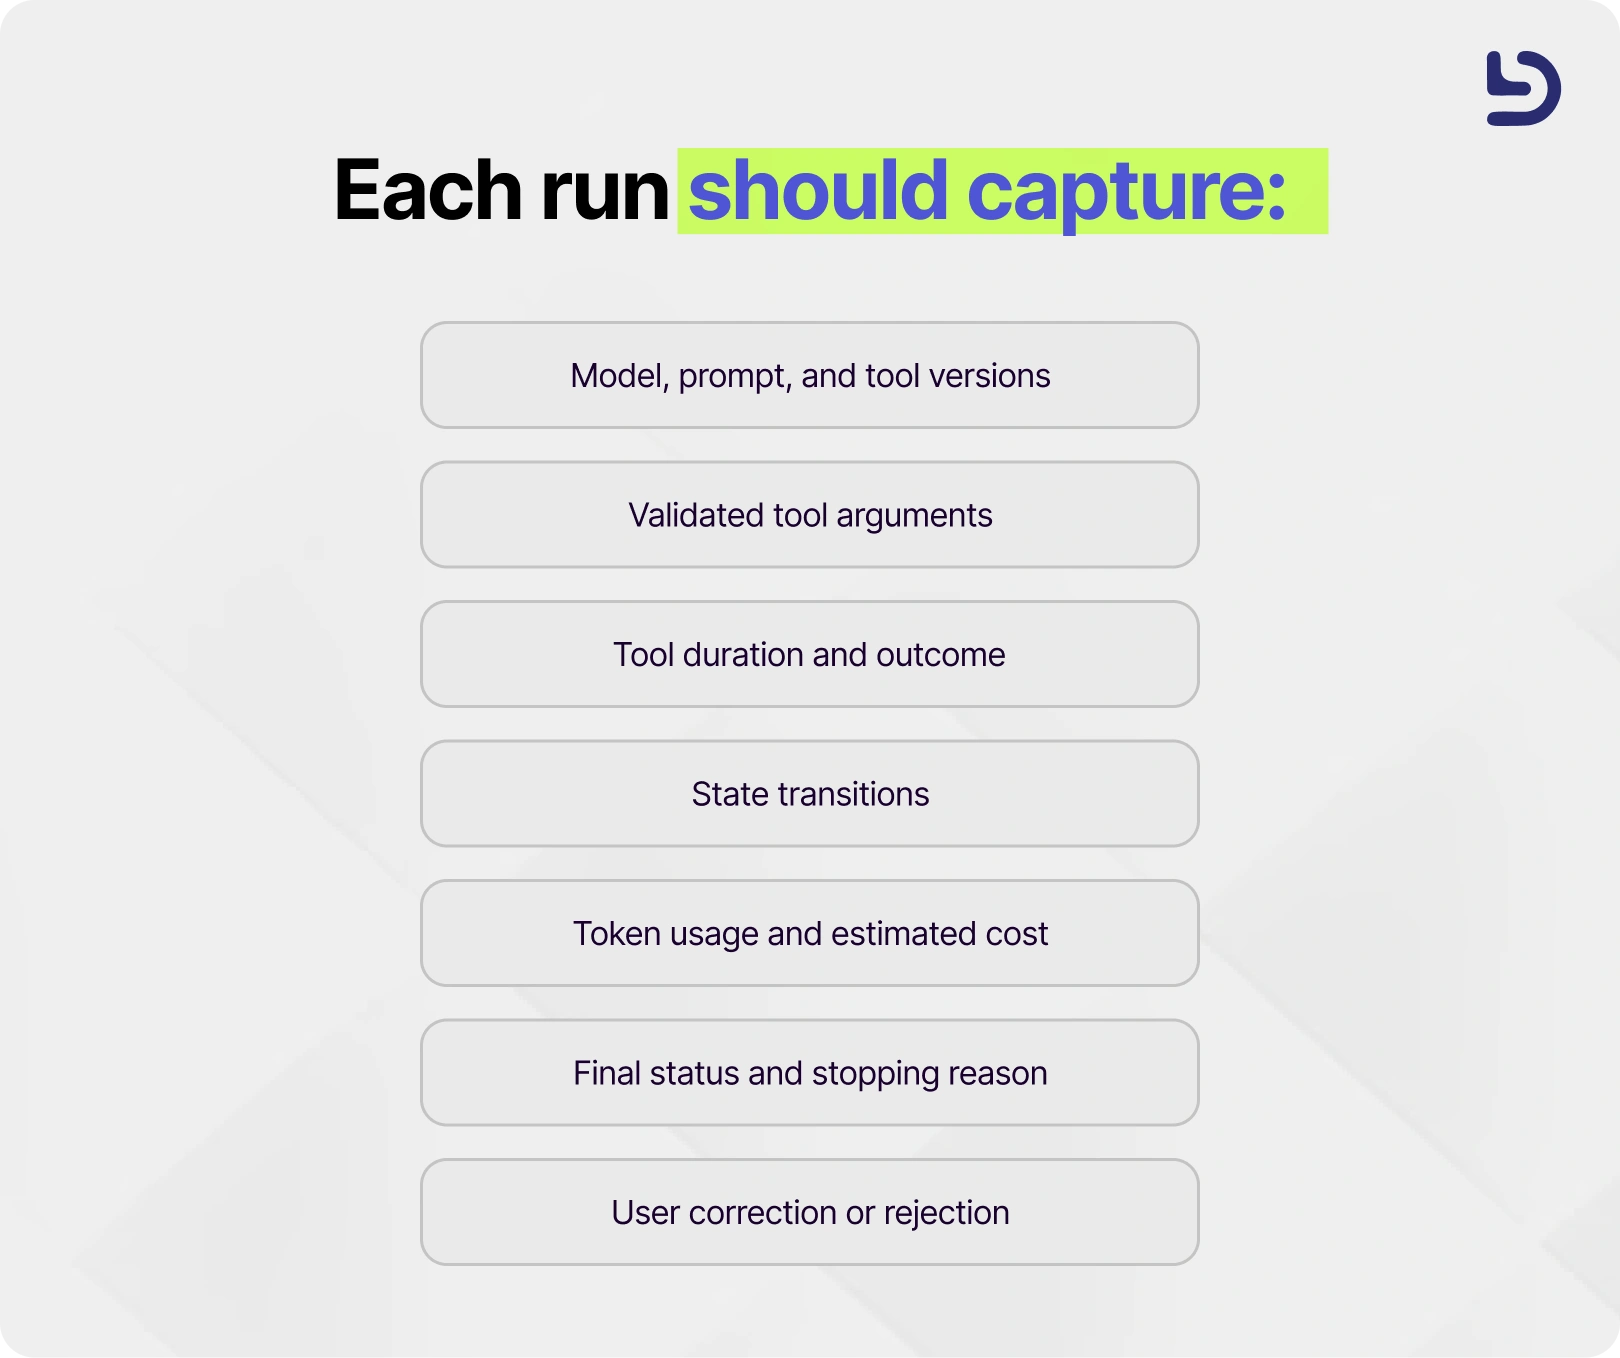
Log the observable inputs, validations, tool calls, state transitions, and outcomes needed to reconstruct a run, while redacting sensitive information.
Retry behavior should depend on the type of failure rather than applying the same strategy to every error. A temporary network problem may justify another attempt, while invalid arguments require the agent or application to change the request before trying again. Write operations also need idempotency controls so that an uncertain response does not result in the same action being executed twice.
Tool validation, authorization, and business rules can be tested without a model. Evaluations should cover realistic requests, ambiguous inputs, permission failures, unavailable dependencies, and cases where the agent must ask for help. Evaluations should also include prompt injection attempts, malicious retrieved content, and tool responses that try to influence the agent’s instructions.
The happy path is usually the easiest part of an agent. The quality of the system becomes visible when information is missing, tools disagree, or the task cannot be completed.
Know when a deterministic workflow is enough
Not every process that includes a language model needs to become an agent. Agent behavior is useful when the system must interpret unstructured input and decide how to proceed based on information discovered during execution.
When the inputs are already structured and the sequence of actions is known, a deterministic implementation is usually easier to test and operate. The model can still support a specific part of the process, such as interpreting a request or producing a summary, without being responsible for controlling the workflow.
In the projects I’ve worked on at Devlane, I’ve found that autonomy is valuable only when it solves a real limitation in the underlying process. In many systems, keeping the execution path explicit results in a more reliable product without reducing the usefulness of the AI component.
Conclusion
Building an AI agent for production requires a clear separation between the decisions that benefit from a language model and the controls that must remain predictable. The model may interpret a request and propose what should happen next, but the application is still responsible for determining whether that action is permitted, preserving the state of the execution, and deciding when the run must stop.
Frameworks can simplify orchestration and tool integration, although they cannot define the operational boundaries of the product. Those decisions depend on the workflow, the consequences of each action, and the way the engineering team needs to investigate failures. A production agent becomes maintainable when an unexpected result can be traced through the system and the execution can be recovered without giving the model more authority than the task requires.
Designing an AI agent involves more than connecting a model to a set of tools. The architecture needs to reflect the workflow, the level of autonomy required, and the risks associated with each action.
At Devlane, we help companies design and build AI-powered products that can operate reliably in real production environments, from early architecture decisions to implementation and ongoing improvement. If you are exploring how an AI agent could support your product or internal operations, talk to our team.
Other Blog Posts
How to Build an AI Agent for Production